
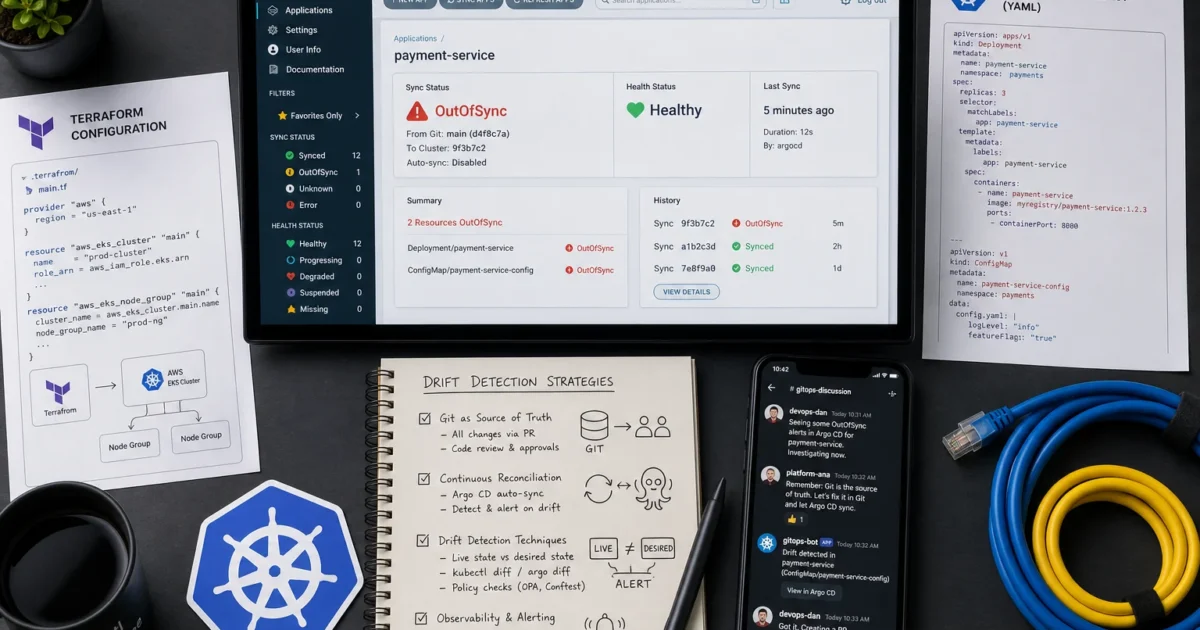
Configuration drift rarely announces itself. A workload stays healthy, the dashboard stays calm, and one live field no longer matches Git. Trouble comes later. A routine sync may overwrite an emergency fix or fight another controller every few minutes.
This setup uses Argo CD, Terraform, Kubernetes role-based access control (RBAC), and alerts. It helps you find, review, fix, and prevent drift. Field ownership is the key decision. Get it wrong, and two reconcilers can spend all day undoing each other’s work.
What Is Kubernetes Configuration Drift?
Desired state is the config in an approved Git repository or Terraform workspace. Live state is what the Kubernetes API stores and controllers run. Configuration drift is a meaningful difference between those states.
Drift can exist when every manifest lives in Git. Someone may run kubectl edit, apply an emergency fix, or trigger an old automation job. Operators, Horizontal Pod Autoscalers (HPAs), admission webhooks, service meshes, and other controllers also change fields after deployment.
Some differences are expected. Each resource, and sometimes each field, needs one owner. Otherwise, drift detection becomes a noisy YAML comparison that nobody trusts.
Prerequisites
Make sure you have:
- A Kubernetes cluster with a supported version for your chosen Argo CD release
- Cluster-admin access for the initial Argo CD installation
- Read access to the workloads being monitored
- A Git repository containing the desired Kubernetes manifests
- A Terraform 1.x workspace if Terraform manages cluster resources
kubectl,argocd,git, and optionallyterraforminstalled- A browser on Windows 11, macOS 14 or later, or another desktop OS
- A backup, stable Git revision, or Terraform state version for rollback
- At least 2 CPU cores and 4 GB of available memory for a small test cluster
The commands use an application named my-app in the production namespace. Replace both values with your own.
Initial setup takes about 20-30 minutes when cluster access and Git credentials already work. Repository login, ingress, and single sign-on can add another hour. Identity systems have a knack for making simple jobs memorable.
Warning: Test installation and reconciliation in a non-production cluster first. Sync, prune, and Terraform operations can replace or delete resources when ownership is unclear.
Step-by-Step Guide
Step 1: Install the Command-Line Tools
Install the clients on the workstation you use to manage Kubernetes. Keep kubectl close to the cluster version. One minor version on either side is the normal supported range.
Windows
Open Windows Terminal as a normal user and run:
winget install --exact --id Kubernetes.kubectl
winget install --exact --id ArgoCD.ArgoCD
winget install --exact --id Hashicorp.Terraform
The --exact flag stops winget from choosing a package with a similar name. Package name collisions are rare, but debugging the wrong binary is a poor use of an afternoon.
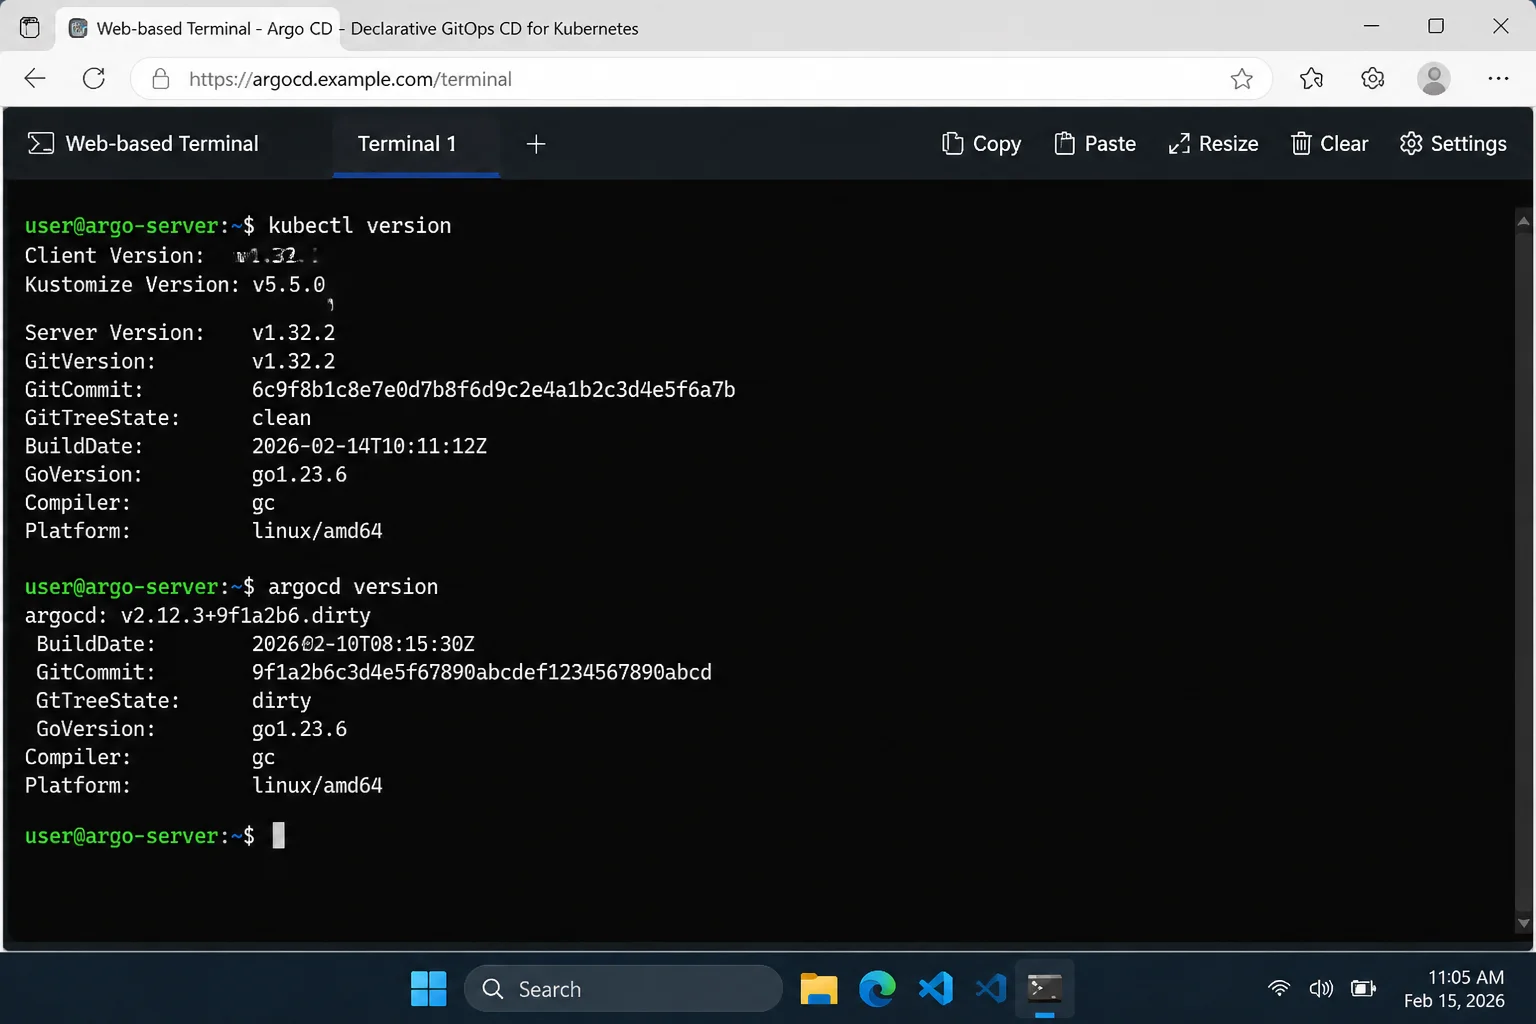
Close and reopen Windows Terminal so it loads the updated PATH. Then check the commands:
kubectl version --client
argocd version --client
terraform version
Expected output includes client version details for all three programs:
Client Version: v1.x.x
argocd: v3.x.x
Terraform v1.x.x
macOS
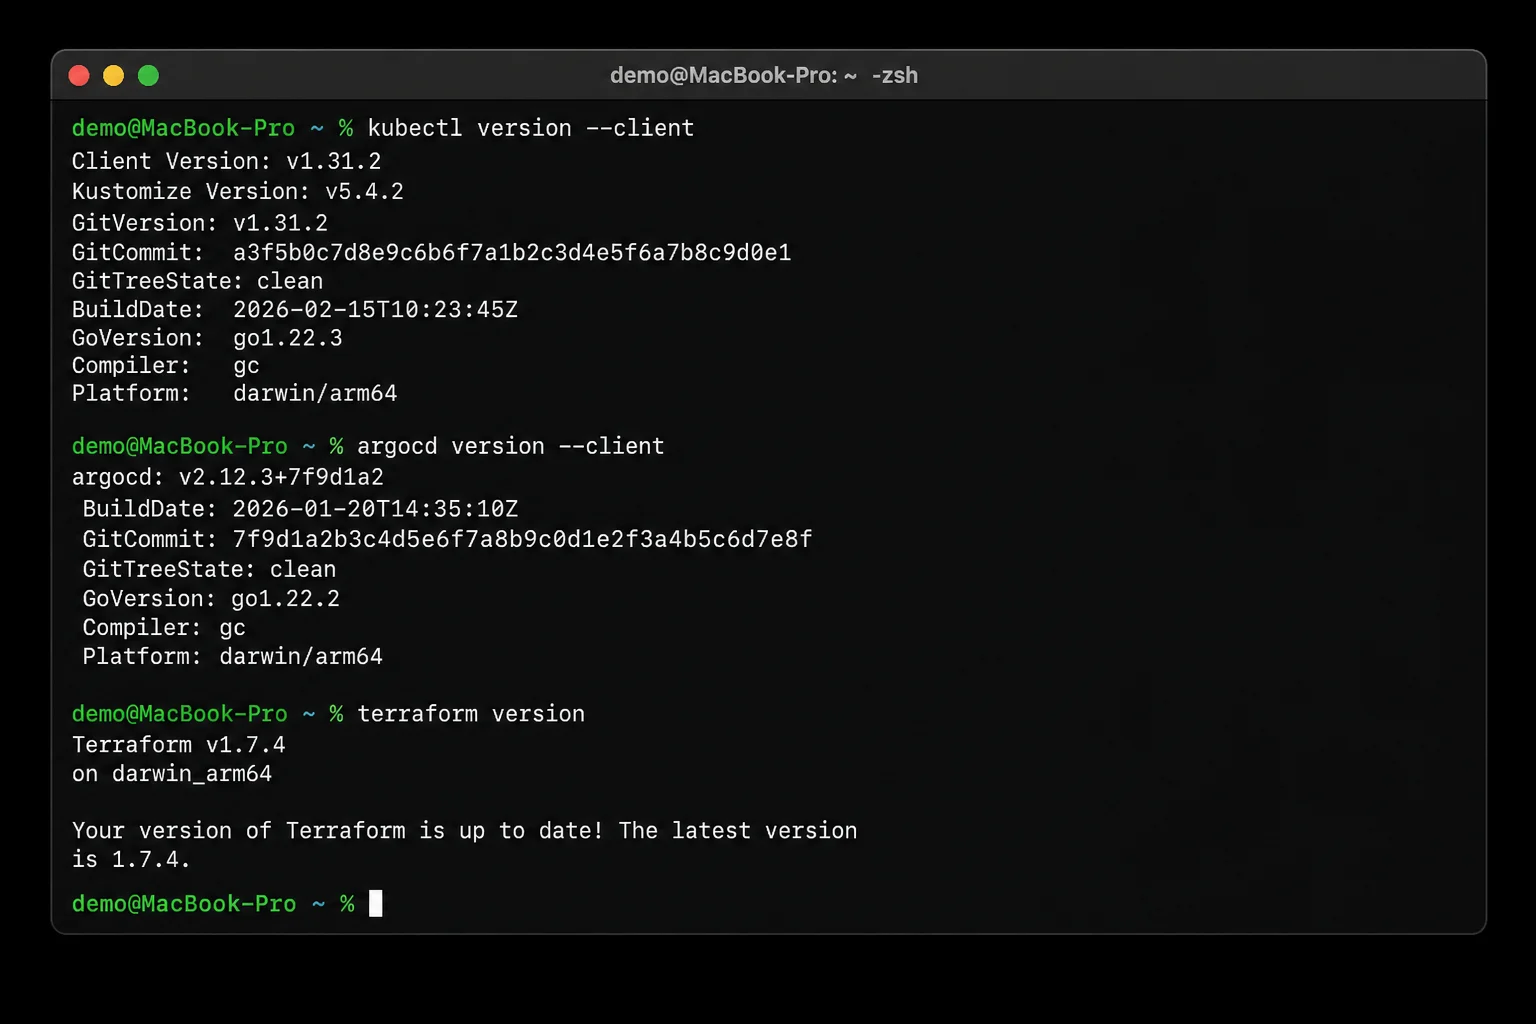
Install the tools with Homebrew:
brew install kubectl argocd terraformCheck them:
kubectl version --client
argocd version --client
terraform version
Homebrew may install newer clients than your cluster uses. That’s usually fine within Kubernetes’ supported version skew. Check compatibility before crossing more than one minor release.
Web
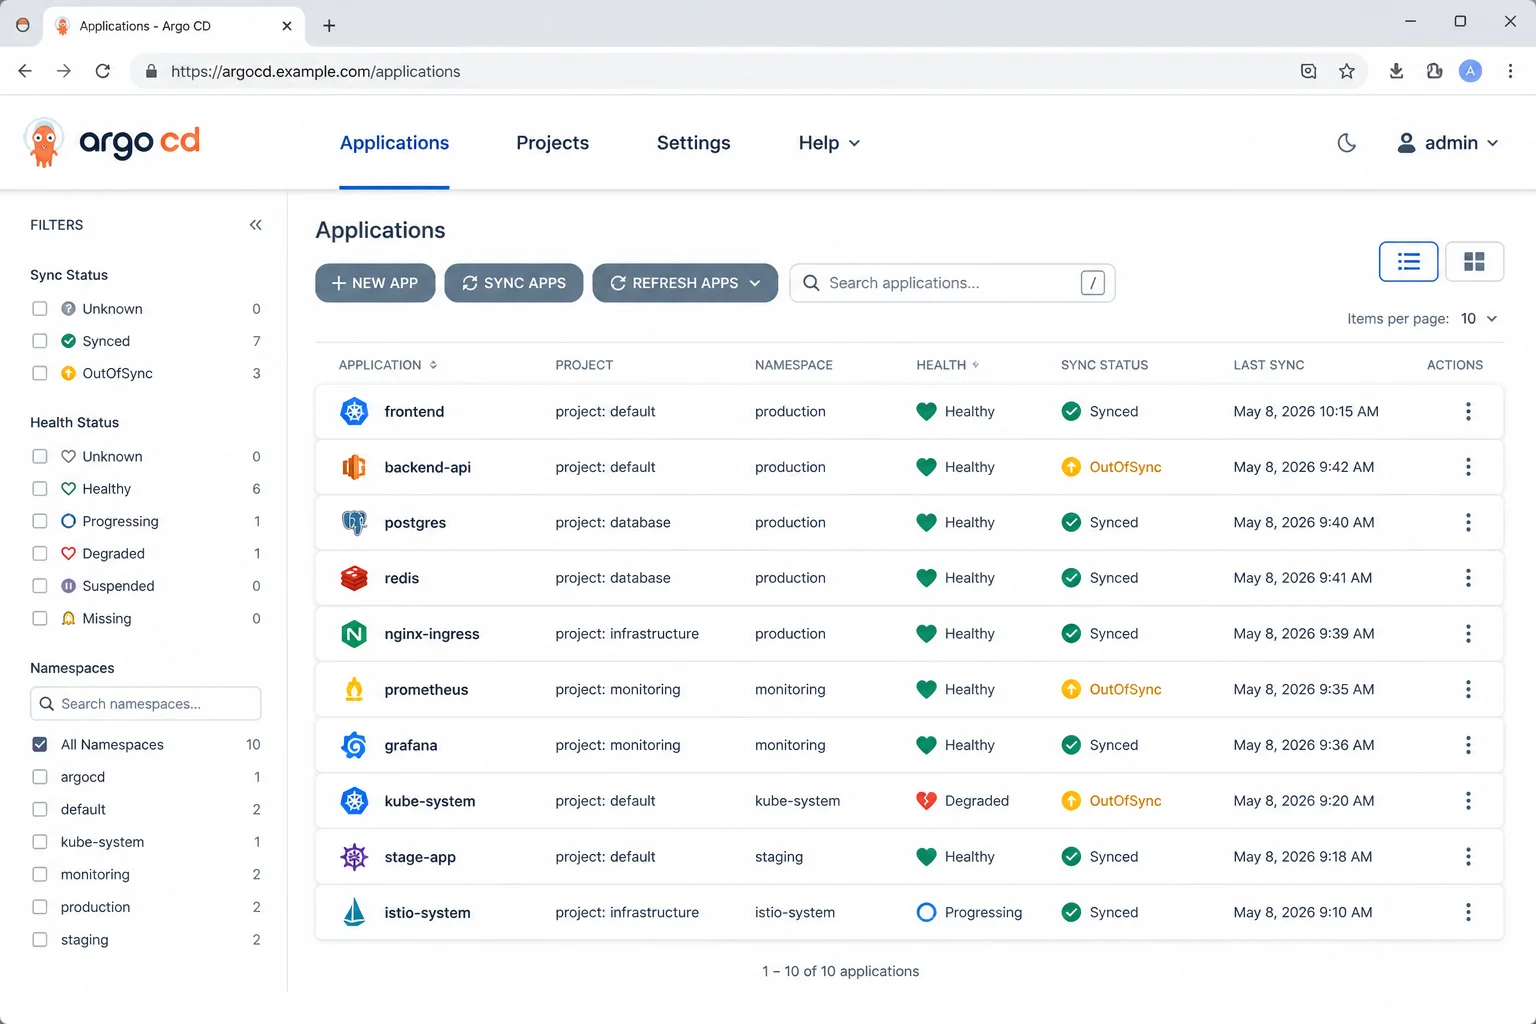
The Argo CD web interface needs no local installation. Use a current Chrome, Edge, Firefox, or Safari release. You’ll still need the command-line tools for installation and detailed checks.
Open your organization’s Argo CD URL after an administrator confirms the address and certificate. A certificate warning on an internal admin service needs investigation, not a reflexive click.
Step 2: Confirm Cluster Access
Select the correct Kubernetes context before installing anything:
kubectl config current-context
kubectl cluster-info
kubectl auth can-i create namespace
Expected result:
your-production-context
Kubernetes control plane is running at https://…
yes
These checks confirm the context name, API connection, and permission to create the namespace. Read the context name twice. Installing Argo CD into the wrong cluster works remarkably well.
If the context is wrong, list the available choices and select the intended cluster:
kubectl config get-contexts
kubectl config use-context YOUR_CONTEXT_NAME
Stop if cluster-info fails or the context points to the wrong environment. Fix a failed permission check before installation too.
Step 3: Install Argo CD in the Cluster
Create the namespace and apply the official stable installation manifest:
kubectl create namespace argocd
kubectl apply --namespace argocd --filename https://raw.githubusercontent.com/argoproj/argo-cd/stable/manifests/install.yaml
The stable URL is handy in a lab, but its target changes with each release. Pin a reviewed Argo CD release in production. That keeps the bootstrap command repeatable next month.
Wait up to 300 seconds for every deployment to become available:
kubectl wait --namespace argocd --for=condition=Available deployment --all --timeout=300s
kubectl get pods --namespace argocd
Expected output shows each pod as Running, usually with all containers ready:
NAME READY STATUS RESTARTS
argocd-application-controller-… 1/1 Running 0
argocd-repo-server-… 1/1 Running 0
argocd-server-… 1/1 Running 0
A Running pod with 0/1 readiness still has a problem. Check readiness, restarts, events, and logs before you continue.
The official Argo CD installation documentation covers production ingress, high availability, and single sign-on. Don’t expose the server publicly with its default administrator account.
For a local test, forward the API server to https://localhost:8080:
kubectl port-forward service/argocd-server --namespace argocd 8080:443Keep that terminal open. The tunnel ends when the process stops. Production installs should use your approved identity provider, TLS certificate, and ingress setup.
Step 4: Register a Git-Managed Application
Create an Argo CD Application that points to the directory containing your manifests:
# ./my-app.yaml
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
  name: my-app
  namespace: argocd
spec:
  project: default
  source:
    repoURL: https://github.com/YOUR_ORGANIZATION/YOUR_REPOSITORY.git
    targetRevision: main
    path: kubernetes/production
  destination:
    server: https://kubernetes.default.svc
    namespace: production
  syncPolicy:
    syncOptions:
      - CreateNamespace=true
targetRevision: main tracks each new commit on that branch. Pin a tag or commit when you need a fixed release. Updates will then require a change to the application definition.
CreateNamespace=true lets Argo CD create production when it’s missing. Skip that option when Terraform or a platform team owns namespaces and their labels.
Apply the definition:
kubectl apply --filename ./my-app.yaml
kubectl get application my-app --namespace argocd
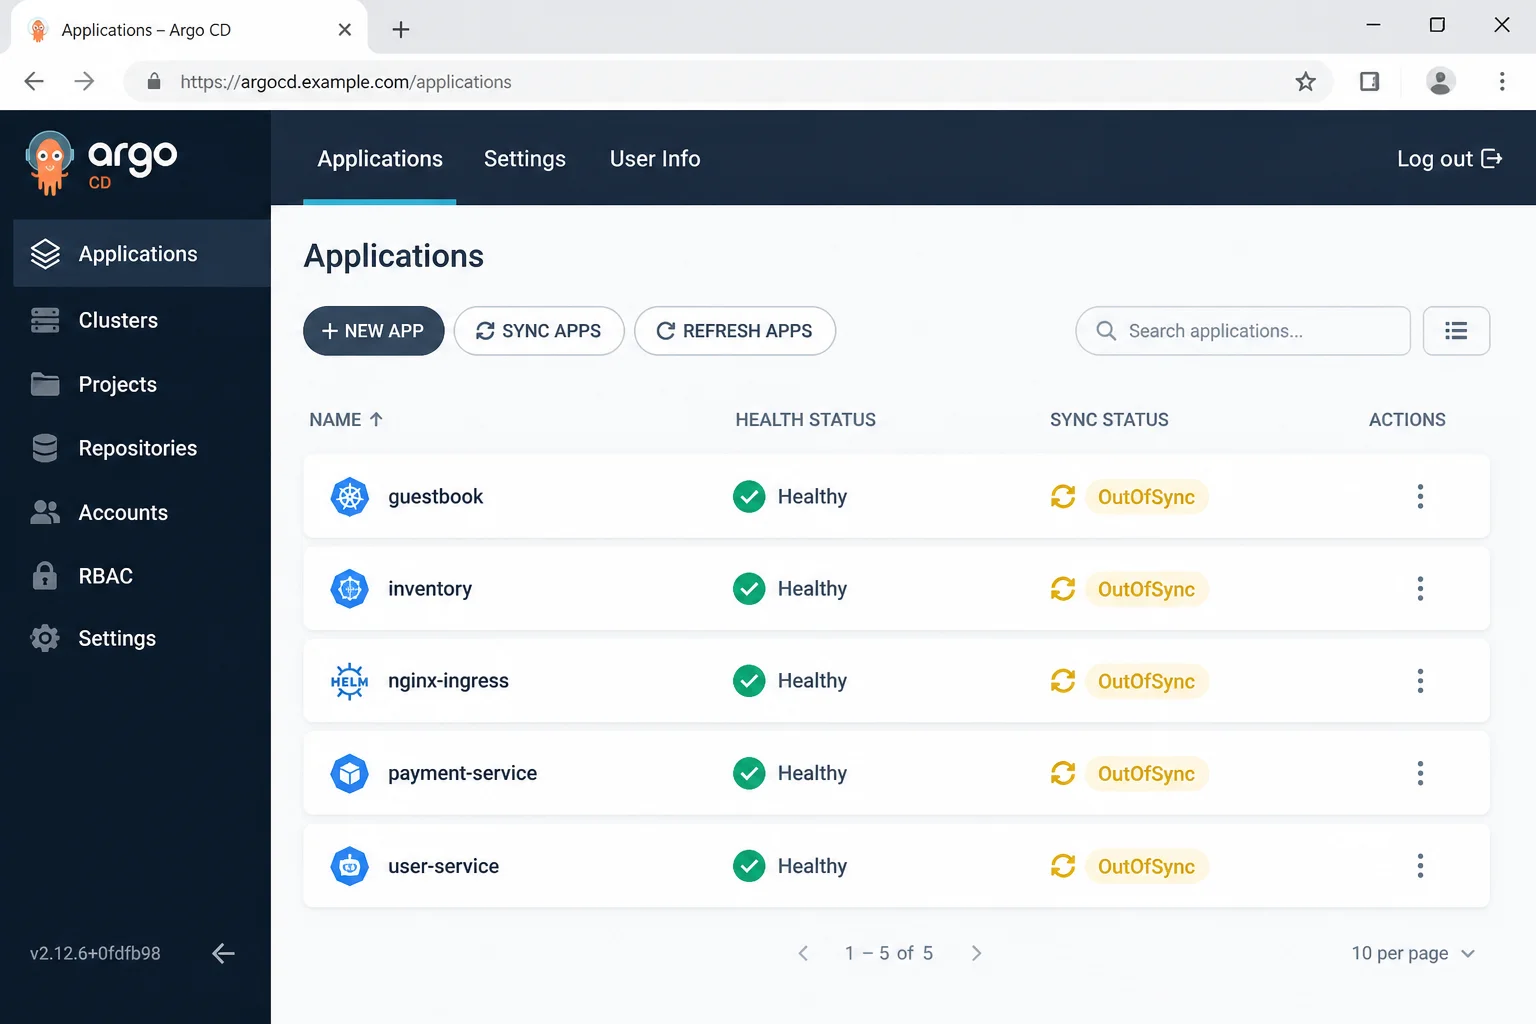
The first result may be OutOfSync because the application hasn’t been synced:
NAME SYNC STATUS HEALTH STATUS
my-app OutOfSync Missing
That result is expected at this stage. Missing means the desired resources aren’t present yet. It doesn’t prove the repository or rendered manifests are valid.
Open the Argo CD URL, select Applications, and find my-app. The dashboard shows Synced, OutOfSync, or Unknown beside each application.
Step 5: Establish Clear Ownership Boundaries
Document ownership before you enable correction. This feels slower than clicking Sync, but it prevents Terraform and Argo CD from trading the same object back and forth.
A practical boundary looks like this:
| Object or field | Authoritative owner |
|---|---|
| Cloud network, cluster, node groups | Terraform |
| Argo CD installation and base services | Terraform or a bootstrap process |
| Deployments, Services, and application configuration | Argo CD |
| Deployment replica count when HPA is active | HPA |
| Injected service-mesh annotations | Admission controller |
| Certificate status and generated data | cert-manager |
Never let Terraform and Argo CD manage the same Kubernetes object. Shared ownership causes noisy plans, repeated rollouts, and controllers that undo each other’s work.
Field ownership can help identify the writer:
kubectl get deployment my-app --namespace production --show-managed-fields --output yamlReview metadata.managedFields[].manager. Values may include argocd-controller, kubectl-edit, an operator name, or an admission component. Those names provide useful evidence.
Managed fields show who claimed or updated fields through Kubernetes’ field-management system. They don’t always explain intent. Older client-side operations can also leave gaps. Check audit logs when the writer matters.
Step 6: Detect Terraform-Managed Drift
Change to the Terraform workspace that owns the resource. Then initialize it and create a saved plan:
cd /absolute/path/to/terraform/workspace
terraform init
terraform plan -out=drift-review.tfplan
terraform init installs the declared providers and sets up the backend. Review provider lock-file changes before accepting them. An unplanned provider upgrade can change value handling and muddy the drift review.
terraform plan refreshes managed objects before comparing live values with the config and state. A change made outside Terraform can appear in the plan. The -out option saves that exact plan for later review and use.
Expected drift output resembles:
# kubernetes_namespace_v1.production will be updated in-place
~ resource “kubernetes_namespace_v1” “production” {
metadata {
~ labels = {
– “temporary-access” = “enabled” -> null
}
}
}Plan: 0 to add, 1 to change, 0 to destroy.
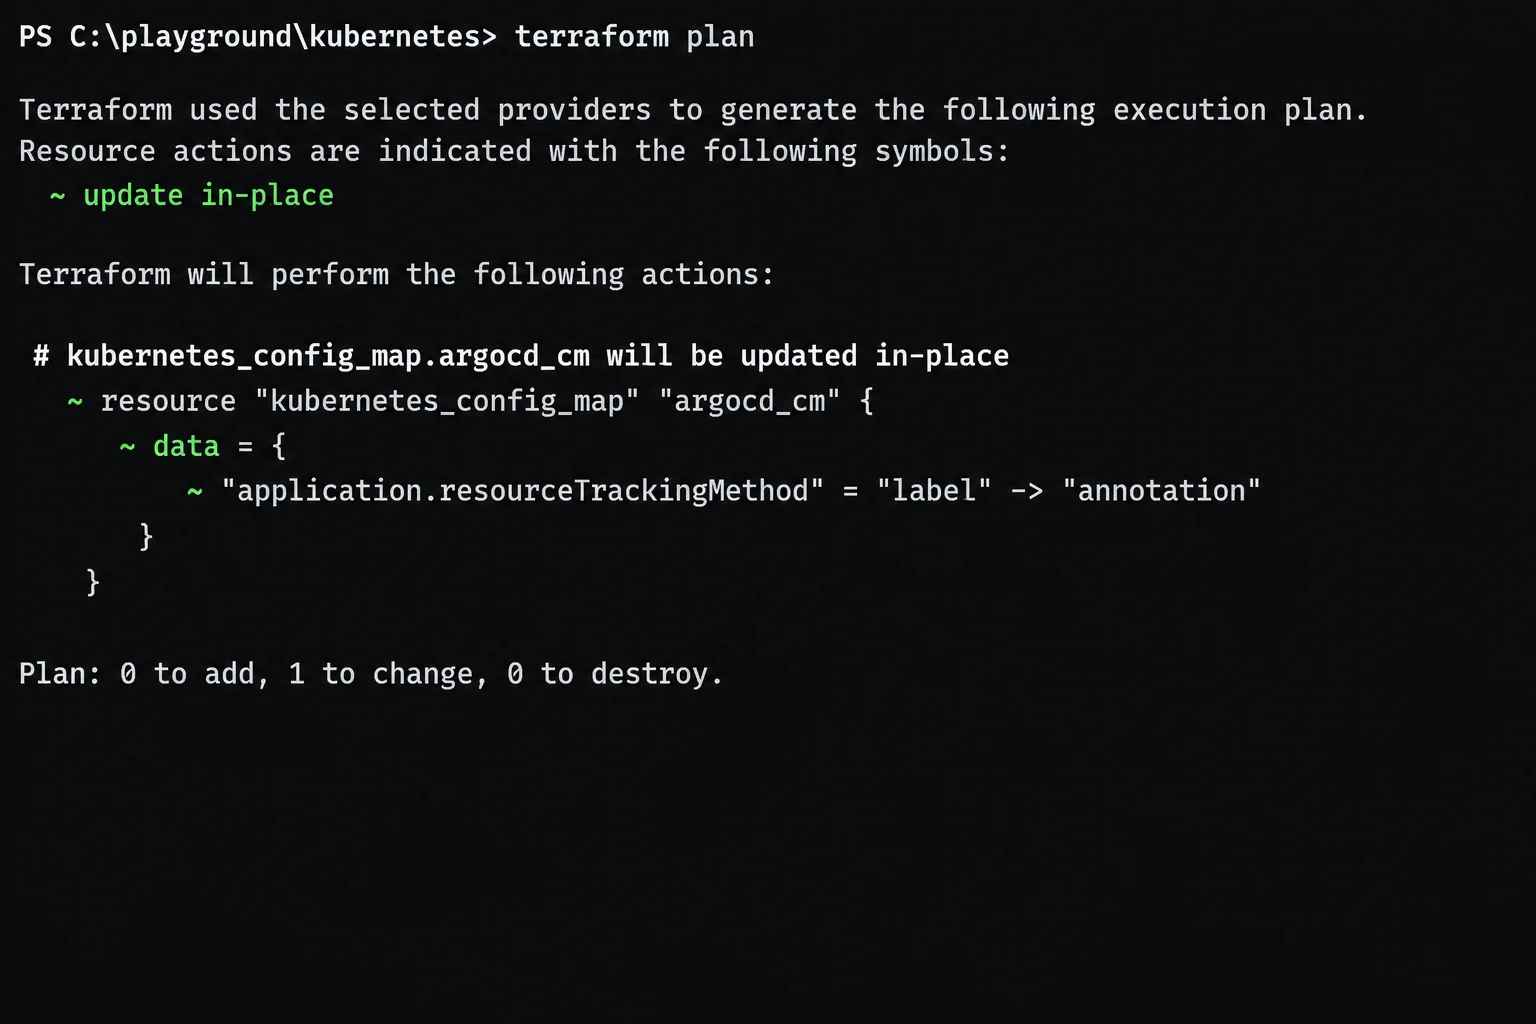
Don’t apply it yet. Check for -/+, must be replaced, destroy actions, immutable fields, or controller-owned values. Provider value handling and stale state can also create apparent differences.
Terraform compares resources it owns well. It’s poor at settling shared ownership. An apply won’t decide which controller should own a field.
Step 7: Investigate Argo CD Drift
Inspect the status, exact changes, and deployment history:
argocd app get my-app
argocd app diff my-app
argocd app history my-app
Expected status fields include:
Sync Status: OutOfSync
Health Status: Healthy
OutOfSync with Healthy means the workload passes its health checks but differs from Git. Review it without panicking. A healthy deployment can still contain an unapproved image, role, or environment variable.
argocd app diff my-app shows the desired and live fields. A nonzero exit status often means it found differences. It doesn’t always mean the command failed. Account for that behavior in shell scripts and CI jobs.
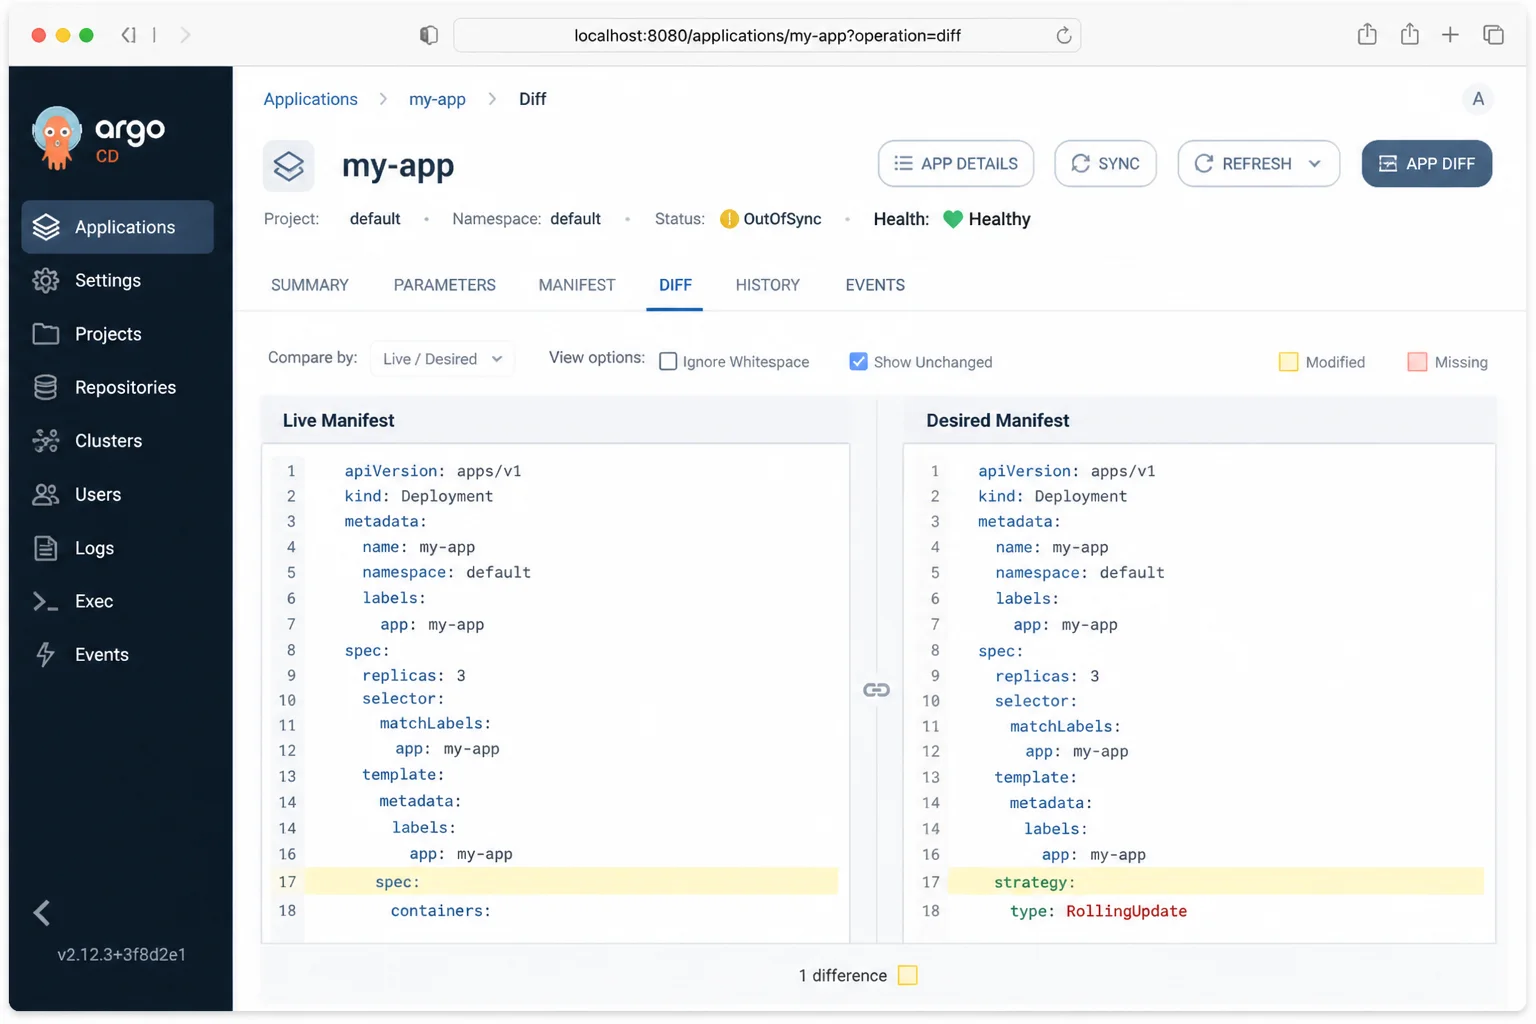
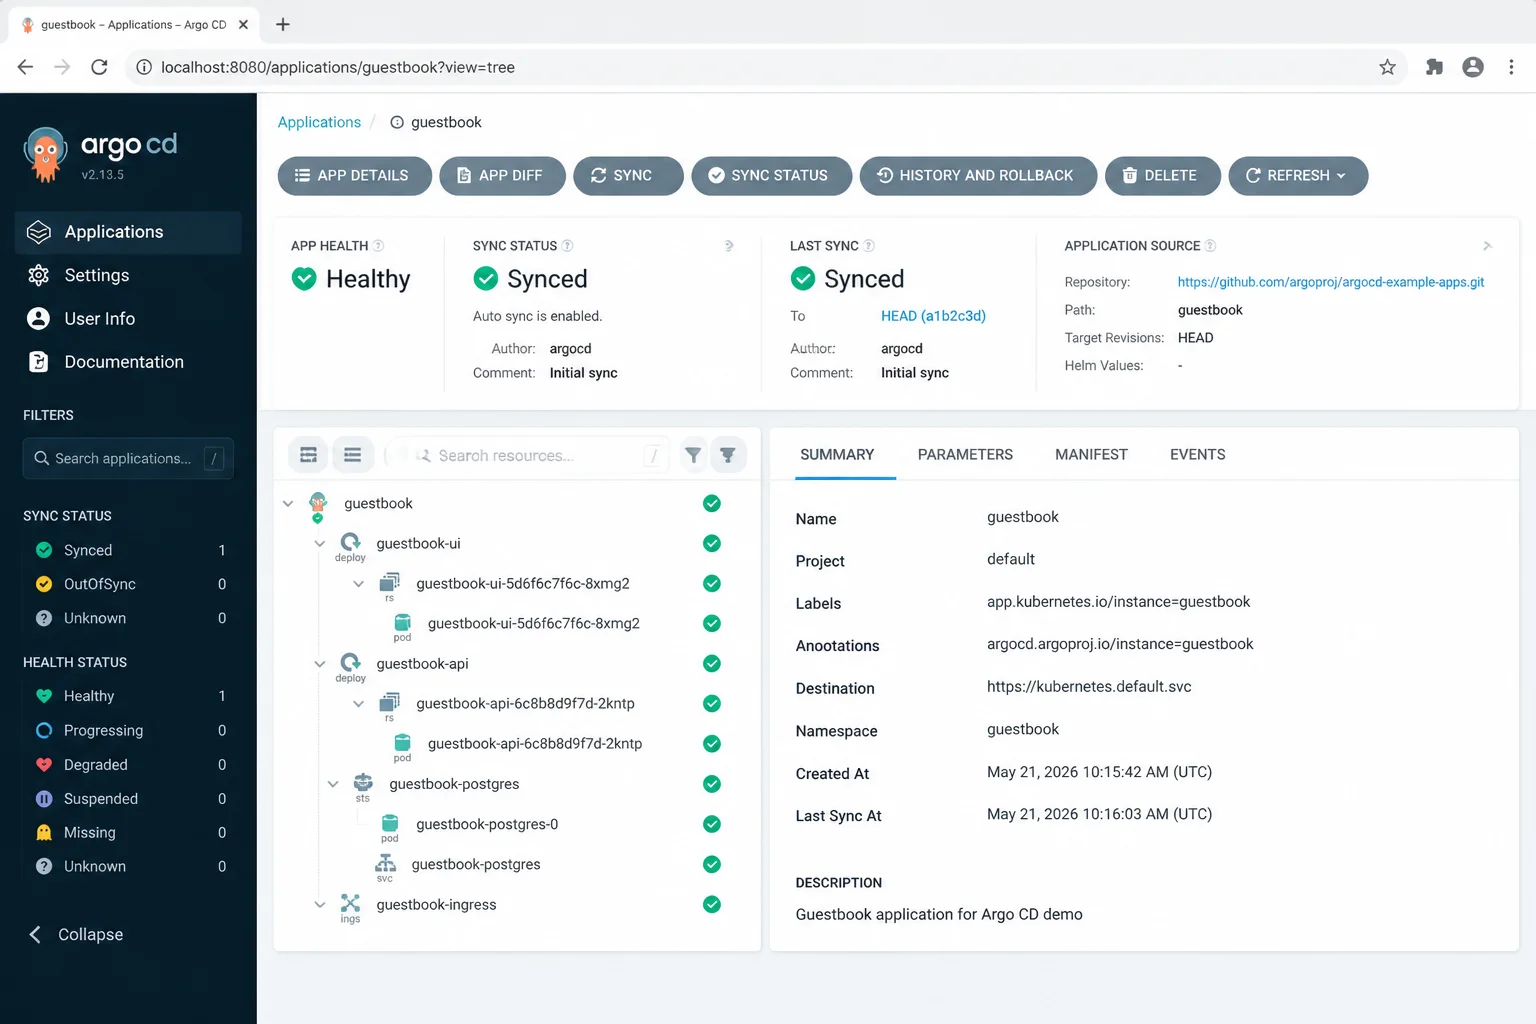
In the web interface, open my-app, select an affected resource, and choose Diff.
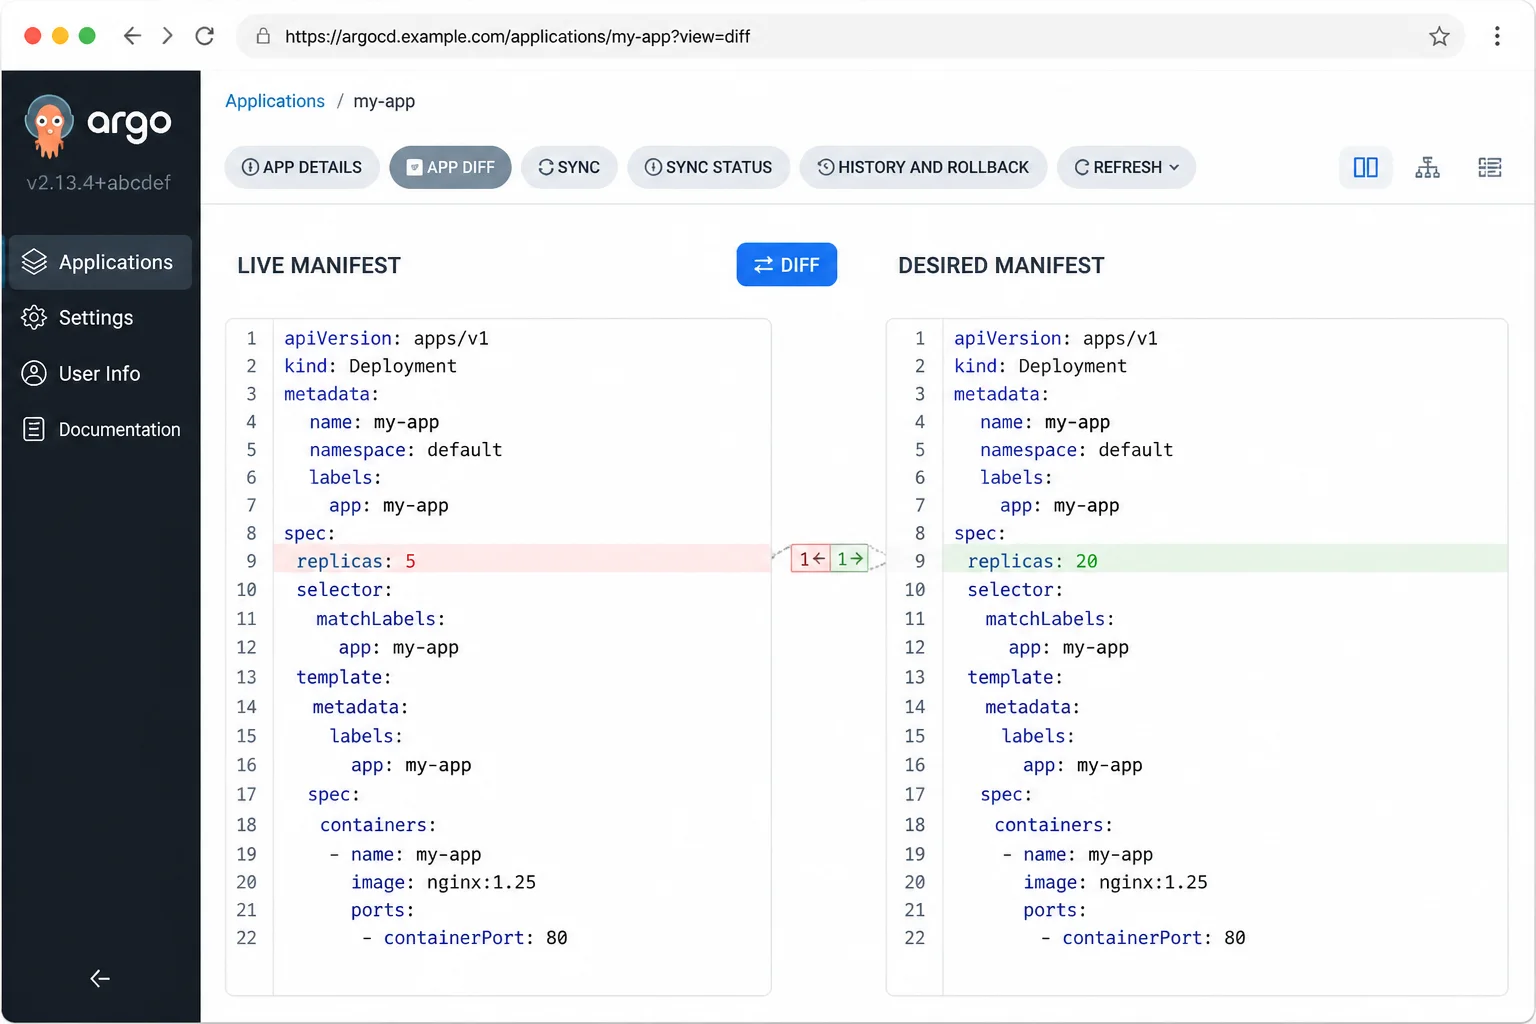
Classify every difference:
- Unauthorized drift: Restore the approved Git or Terraform value and remove the writer’s access.
- Intentional but undocumented: If an emergency live change is still needed, commit it to Git first. Use review and the normal deployment path to keep it.
- Legitimately controller-managed: Give that field to the controller. Exclude only that field from GitOps comparison or sync.
Restore the Git value when Git is correct and the live edit was accidental, expired, or unauthorized. Commit an emergency value when reverting it would recreate the incident or remove a needed fix.
This decision needs human judgment. Diff tools show two values, but they can’t decide which one keeps checkout working at 02:00.
Step 8: Correct Approved Drift Safely
For Terraform-managed drift, inspect the saved plan again:
terraform show drift-review.tfplanThis reads the saved artifact instead of making a fresh plan. If the environment changed after planning, create and review a new plan. Don’t apply stale assumptions.
Apply the exact reviewed plan after you approve any replacements and deletions:
terraform apply drift-review.tfplanFor Argo CD, open the application and click Sync. Select only resources owned by Argo CD. Review the options, and keep pruning clear unless you intend to delete resources.
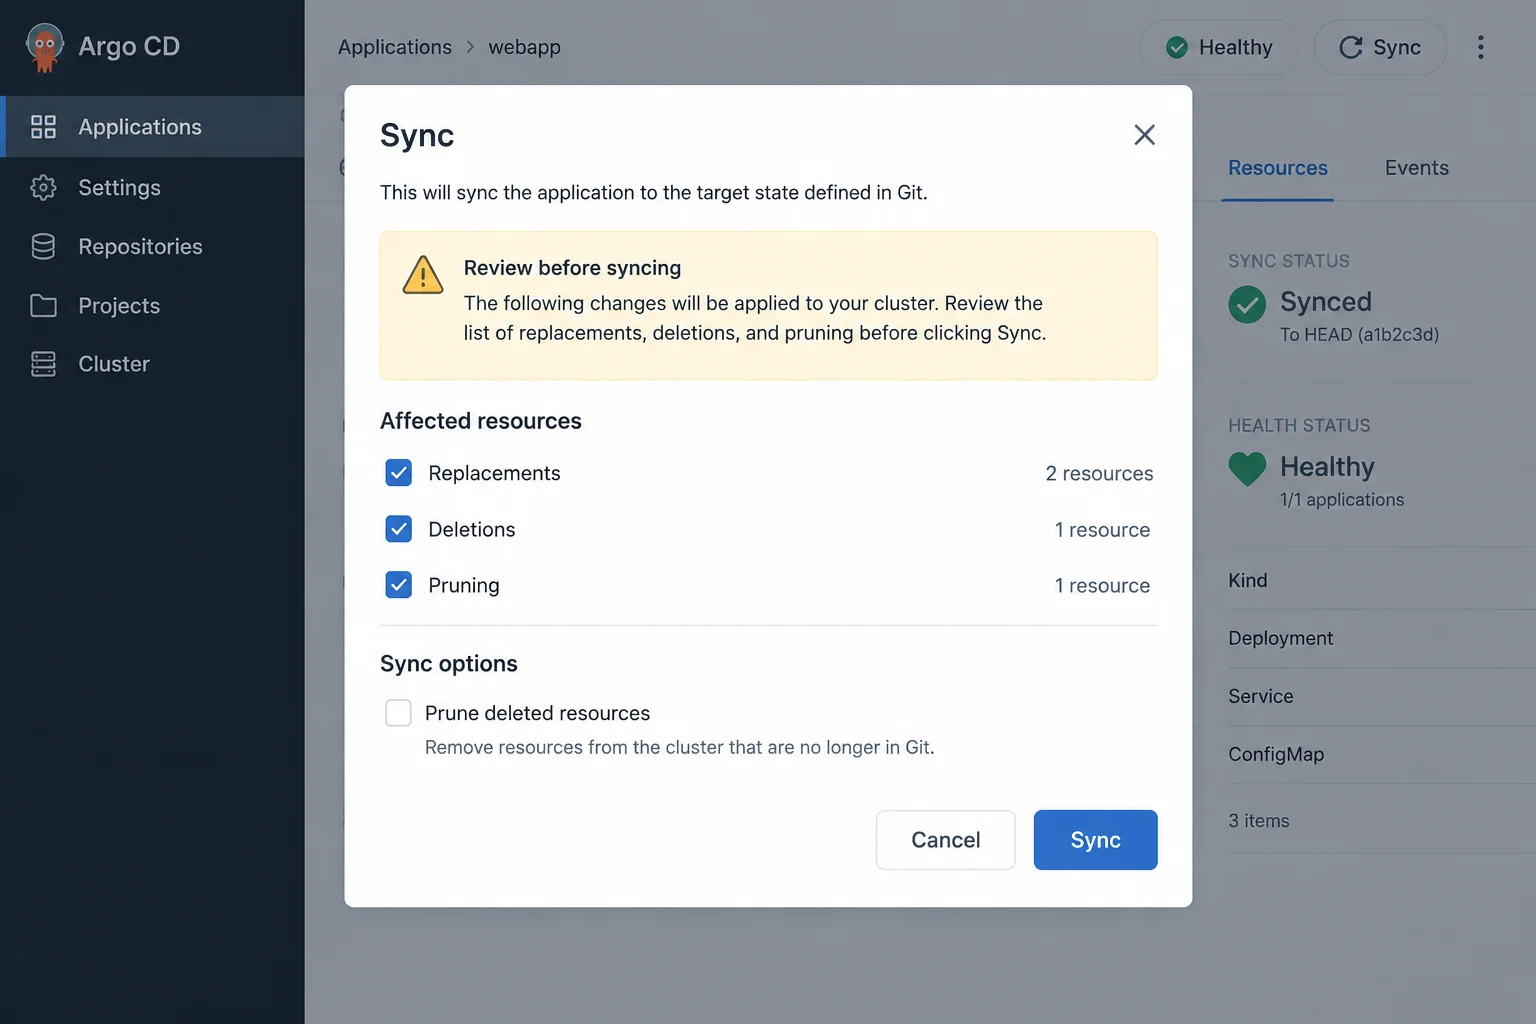
Selective sync can correct one ConfigMap or Deployment without touching an unrelated healthy resource. You still need to inspect immutable fields and rollout effects.
Treat pruning with extra suspicion. It deletes managed resources removed from Git. That’s useful when planned and rather final when somebody moved a directory by mistake.
Step 9: Validate Health and Preserve Rollback
After correction, check sync status, workloads, events, and rollout state:
argocd app get my-app
kubectl get deployments,pods --namespace production
kubectl rollout status deployment/my-app --namespace production --timeout=300s
kubectl get events --namespace production --sort-by=.lastTimestamp
The 300-second timeout stops a stuck rollout from holding the terminal forever. Five minutes suits a small application. Increase it for slow image pulls or long readiness checks.
Expected results are Synced, Healthy, ready pods, and a completed rollout:
Sync Status: Synced
Health Status: Healthy
deployment “my-app” successfully rolled out
Also check application metrics, logs, readiness probes, error rates, and external dependencies. Kubernetes readiness confirms that the probe passed. It doesn’t prove users can complete a transaction.
Keep the previous Git commit, Argo CD history entry, backup, and Terraform state version until the workload stays stable. Set that window per service. An internal API may need 15 minutes, while a low-traffic batch job may need one full run.
Step 10: Restrict Manual Production Changes
Give most operators read access and route lasting changes through pull requests. This example permits inspection in production. It denies create, patch, update, and delete operations:
# ./production-viewer-rbac.yaml
apiVersion: rbac.authorization.k8s.io/v1
kind: Role
metadata:
  name: production-viewer
  namespace: production
rules:
  - apiGroups: ["", "apps", "batch"]
    resources:
      - pods
      - pods/log
      - services
      - configmaps
      - deployments
      - replicasets
      - jobs
      - cronjobs
    verbs: ["get", "list", "watch"]
---
apiVersion: rbac.authorization.k8s.io/v1
kind: RoleBinding
metadata:
  name: production-viewers
  namespace: production
subjects:
  - kind: Group
    name: production-viewers
    apiGroup: rbac.authorization.k8s.io
roleRef:
  kind: Role
  name: production-viewer
  apiGroup: rbac.authorization.k8s.io
The Role applies only to the production namespace. The three verbs support inspection and watch-based tools without allowing resource changes.
Apply and test it:
kubectl apply --filename ./production-viewer-rbac.yaml
kubectl auth can-i patch deployments --namespace production --as-group=production-viewers --as=example-user
Expected result:
no
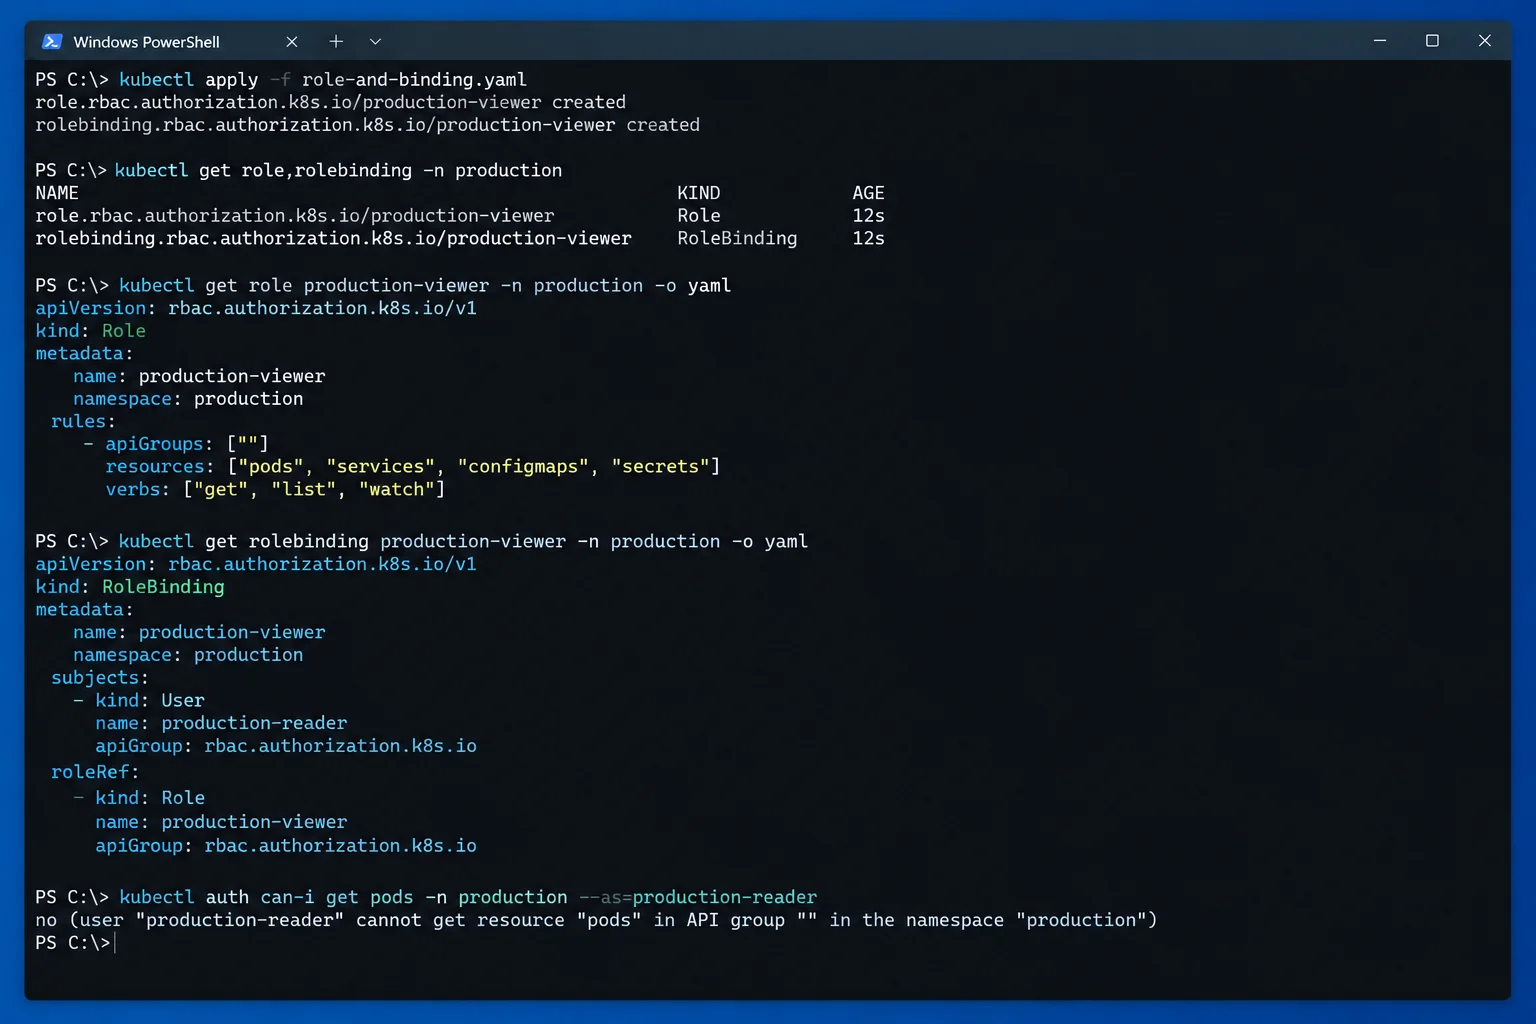
Test with impersonation before you assign the group broadly. Check allowed actions such as get pods too. A policy that blocks routine diagnosis encourages requests for wider access.
Keep tightly controlled break-glass access for incidents. Require an incident record, short-lived credentials, audit logs, and a follow-up Git commit or rollback. Emergency access without cleanup is permanent access with better branding.
Configuration
Configure Safe Argo CD Self-Healing
Enable automatic self-healing after ownership is clear and diffs are quiet. Health checks must work, and the workload should pass manual reconciliation tests. Start with one low-risk application. Watch it through several normal deployment cycles.
spec:
  syncPolicy:
    automated:
      enabled: true
      prune: false
      selfHeal: true
    syncOptions:
- RespectIgnoreDifferences=true| Setting | Purpose | Practical guidance |
|---|---|---|
selfHeal | Reapplies desired Git values after live drift | Enable per tested application, not globally by assumption |
prune | Deletes managed resources removed from Git | Leave off until deletion and rollback behavior are tested |
ignoreDifferences | Excludes fields legitimately owned elsewhere | Match the exact resource and JSON pointer |
RespectIgnoreDifferences=true | Preserves ignored fields during sync | Use when ignored fields must not be overwritten |
| Server-side diff | Includes API-server defaulting and mutation behavior | Useful when client-side comparisons produce false positives |
ignoreDifferences may hide comparison noise while sync still writes the desired value. Add an applicable RespectIgnoreDifferences=true setting when sync must preserve ignored fields. Otherwise, the ownership fight continues behind a greener dashboard.
For an HPA-owned replica count, use a narrow rule:
spec:
  ignoreDifferences:
    - group: apps
      kind: Deployment
      name: my-app
      namespace: production
      jsonPointers:
        - /spec/replicas
  syncPolicy:
    syncOptions:
      - RespectIgnoreDifferences=true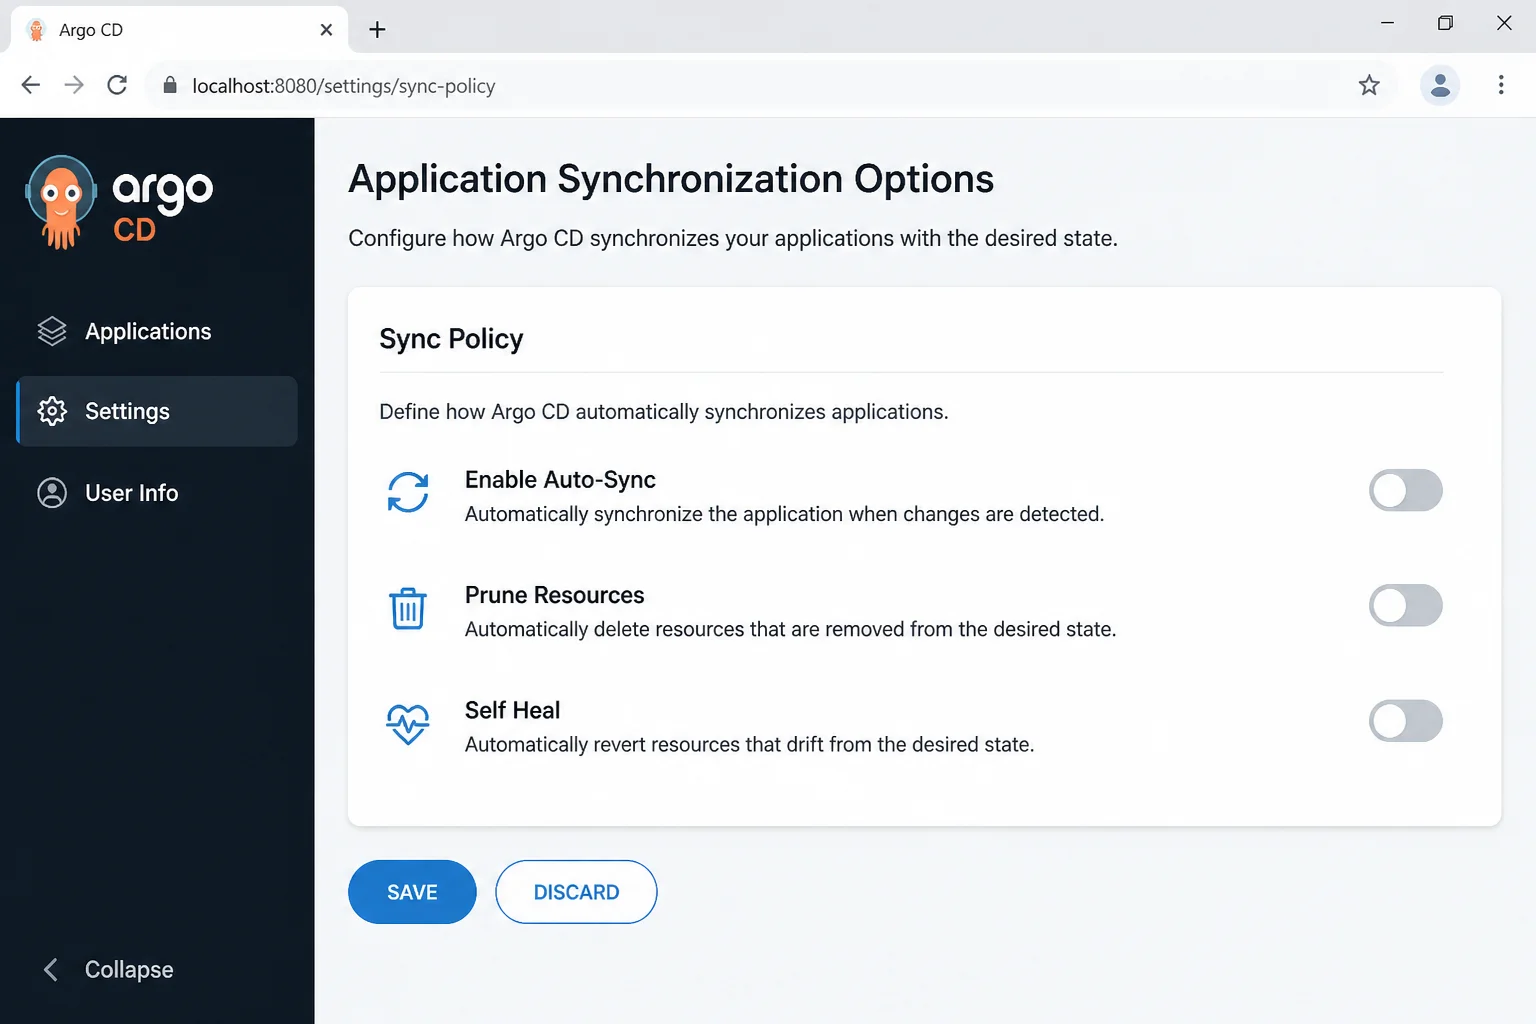
Ignoring /spec/replicas for one HPA-controlled Deployment is reasonable. Broad rules can hide security and operational drift. Avoid ignoring all annotations, container security contexts, images, or whole resource types.
Self-healing restores known values quickly. It’s bad at understanding emergency intent. Tie break-glass procedures to Git updates or a documented pause in reconciliation.
Monitor Recurring Drift
Expose Argo CD metrics to your existing Prometheus stack. Alert when an application stays out of sync. Metric labels vary by Argo CD version and monitoring setup. Check them in Prometheus before you deploy this rule:
apiVersion: monitoring.coreos.com/v1
kind: PrometheusRule
metadata:
  name: argocd-drift
  namespace: monitoring
spec:
  groups:
    - name: argocd-drift
      rules:
        - alert: ArgoCDApplicationOutOfSync
          expr: argocd_app_info{sync_status!="Synced"} == 1
          for: 10m
          labels:
            severity: warning
          annotations:
            summary: "Argo CD application is not synchronized"
            description: "Review ownership and the desired-versus-live diff before correction."
        - alert: ArgoCDApplicationUnhealthy
          expr: argocd_app_info{health_status=~"Degraded|Missing|Unknown"} == 1
          for: 5m
          labels:
            severity: critical
          annotations:
            summary: "Argo CD application health requires investigation"
The 10-minute delay filters short sync transitions. The 5-minute health threshold flags broken or missing workloads sooner. Match both values to normal rollout time. A 12-minute deployment will otherwise page on every release.
Alert on lasting drift and failed reconciliation. Don’t alert on each brief state change. Track repeat drift by application, resource, and field owner. Kubernetes audit logs can identify manual and automated writers that keep returning.
Raw whole-cluster YAML snapshots make poor primary baselines. They include status, timestamps, generated metadata, and controller output. They also become stale after approved changes. Keep Git or infrastructure as code as the maintained baseline.
Snapshots still help during incident response and forensic review. Treat them as evidence from one point in time. Don’t feed them back into the API as configuration.
Tips and Troubleshooting
Application repeatedly becomes OutOfSync
Why it happens: An HPA, operator, webhook, automation job, or person keeps rewriting a field.
Fix: Run argocd app diff my-app, inspect metadata.managedFields, and identify the writer. Stop unauthorized automation, commit an intended change, or add a narrow ownership rule for a trusted controller.
If the same field changes on a fixed schedule, check CronJobs and external automation first. A five-minute drift cycle often has a five-minute scheduler behind it.
Terraform proposes unexpected replacement or deletion
Why it happens: State may be stale, a provider may change the value’s format, or another tool may own the object.
Fix: Stop before applying. Run terraform show drift-review.tfplan, confirm the resource owner, inspect the live object, and review the state backend history. Move ownership instead of accepting a permanent Terraform-versus-Argo CD conflict.
A replacement marker needs more attention than the final plan count. One replaced namespace or cluster resource can affect hundreds of objects, even when Terraform reports one change.
The diff contains defaulted or generated values
Why it happens: The API server, an admission webhook, or a controller changed the submitted object.
Fix: Identify the field manager and use server-side diff where supported. Ignore only the exact valid field. Don’t hide security contexts, image tags, role permissions, or network policy changes to make the dashboard green.
Defaults can change after Kubernetes or webhook upgrades. Keep ignore rules narrow so new security-related differences still appear.
Sync may disrupt a healthy workload
Why it happens: The proposed change touches immutable fields, triggers replacement, includes pruning, or changes rollout behavior.
Fix: Use selective sync, leave pruning disabled, check readiness and disruption budgets, and test outside production. Correct the smallest owned resource set first. Then watch rollout status and application metrics.
For one Deployment, check maxUnavailable, maxSurge, and the PodDisruptionBudget before syncing. A valid manifest can still remove too much capacity during rollout.
Drift returns after every correction
Why it happens: The correction fixed the changed value, but the original writer stayed active.
Fix: Review audit logs, managed fields, scheduled jobs, webhooks, and RBAC bindings. Remove unneeded write access and require production changes through Git-based review.
Repeated correction can cause constant pod restarts or API load. Pause automatic self-healing while you identify the writer if the live change poses no immediate risk.
Argo CD shows Unknown instead of OutOfSync
Why it happens: Repository access, manifest generation, cluster credentials, or the application controller may have failed.
Fix: Inspect application conditions and controller logs:
argocd app get my-app
kubectl logs deployment/argocd-application-controller --namespace argocd --tail=200
kubectl logs deployment/argocd-repo-server --namespace argocd --tail=200
The --tail=200 flag keeps the first check readable. Increase it or add --since=30m when the failure started earlier.
Repository login failures usually appear in repo-server logs. Cluster access and reconciliation failures tend to appear in application-controller logs. That split saves a fair amount of random log browsing.
For Amazon EKS integrations, also consult the official EKS Argo CD troubleshooting guide.
Wrapping Up
| Step | Action | Applies To |
|---|---|---|
| Detect | Run a reviewed plan or desired-versus-live diff | Terraform and Argo CD |
| Review | Classify drift and confirm field ownership | Every difference |
| Correct | Apply the saved plan or selectively sync | Approved owned resources |
| Validate | Check health, rollouts, events, and metrics | Corrected workloads |
| Prevent | Use RBAC, Git review, audit logs, and alerts | Production clusters |
Drift monitoring works when ownership is clear. Argo CD handles Git-managed application resources well. Terraform handles its infrastructure, and controllers keep their assigned fields. Cross those boundaries and you’ll get noisy plans, repeated changes, and occasional outages.
Start with manual review, narrow exceptions, and pruning disabled. After several clean sync cycles, enable self-healing per application. Alert on drift that lasts 10 minutes. Automatic correction everywhere sounds handy, but a slower rollout tends to survive production.